Official Website link
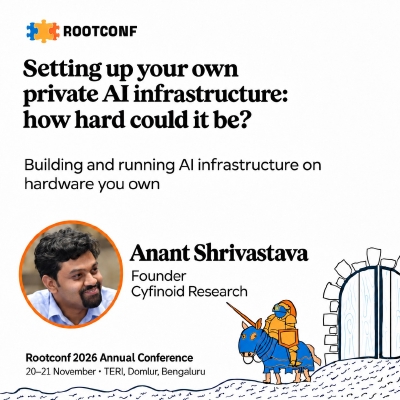
Date: November 20, 2026 | 10:50 AM - 11:25 AM IST Event: RootConf 2026 Annual Conference Location: Auditorium, Ground Floor, TERI, Domlur II Stage, Bangalore Format: 35-minute Talk Level: Intermediate
Overview
Most private AI conversations sit at two ends: hosted API subscriptions on one side, datacenter-scale GPU clusters on the other. This talk covers the space in between, running AI infrastructure on hardware you directly own. That can be a workstation with a GPU, an Apple machine with unified memory, or a few machines joined over a private network.
The session opens with why I own this infrastructure at all. SaaS API access bills per token, imposes rate limits that move with the platform, and leaves reliability outside your control. Private is not cheaper once hardware, electricity, and your own time are counted, but it buys control over the hardware, the models that run on it, and who gets access.
From there it walks the full build: hardware selection between dedicated GPUs and unified memory machines, VRAM planning across weights, KV cache and buffers, and the power and cooling costs people forget. Then the software stack: inference gateways such as Ollama and LM Studio, llama-swap for model routing and lifecycle management, and runtimes including llama.cpp, vLLM, and MLX. Model selection, quantization, performance measurement, and day-2 maintenance follow, ending with the security work: threat modeling the environment, keeping ports off the internet, and containing AI coding agents.
Owning the stack shows up in the results too. The deck includes llama.cpp PRs merged after running owned Intel Arc hardware, and closes with llm-playbooks, a public repository of configs, optimization tips, and environment notes. An earlier version of this session was presented at the OWASP 25th Anniversary Virtual Conference in September 2026 with a stronger security focus; this one leans into hardware and the day-to-day of operating the stack.
Key Topics
- Why own AI infrastructure: control over hardware, models, data, and access, and why cost savings alone is a poor justification
- Hardware decisions: dedicated GPU vs unified memory, dense vs MoE models, VRAM math (weights + KV cache + buffers), power draw, thermals, and noise
- Quantization and VRAM fit: the gap between what can run and what is comfortable to operate every day
- The software stack: inference gateways, llama-swap for model routing, runtimes (llama.cpp, vLLM, MLX), and compatibility issues across vendors
- Remote access without exposing ports: Tailscale, WireGuard, and SSH port forwarding
- Living with the infrastructure: model updates, memory pressure, stability over the latest feature, and measuring prefill and token generation at real context depth
- Security and isolation: threat modeling the stack and containing AI coding agents
Related Project
The containment segment of this talk is AIDC, the AI Dev Container setup I built after asking “how hard could it be?” in June 2026. It runs AI coding agents inside hardened, project-specific containers instead of handing them the whole host, with package traffic routed through a gateway and session logs pulled back to the base system so observability tools see what the agent did.